Vlaser: Vision-Language-Action Model with Synergistic Embodied Reasoning
Abstract
While significant research has focused on developing embodied reasoning capabilities using Vision-Language Models (VLMs) or integrating advanced VLMs into Vision-Language-Action (VLA) models for end-to-end robot control, few studies directly address the critical gap between upstream VLM-based reasoning and downstream VLA policy learning. In this work, we take an initial step toward bridging embodied reasoning with VLA policy learning by introducing Vlaser -- a Vision-Language-Action Model with synergistic embodied reasoning capability, which is a foundational vision-language model designed to integrate high-level reasoning with low-level control for embodied agents. Built upon the high-quality Vlaser-6M dataset, Vlaser achieves state-of-the-art performance across a range of embodied reasoning benchmarks—including spatial reasoning, embodied grounding, embodied QA, and task planning. Furthermore, we systematically examine how different VLM initializations affect supervised VLA fine-tuning, offering novel insights into mitigating the domain shift between internet-scale pre-training data and embodied-specific policy learning data. Based on these insights, our approach achieves state-of-the-art results on the WidowX benchmark and competitive performance on the Google Robot benchmark. The code, model and data are available at https://github.com/OpenGVLab/Vlaser/.
Overview
Vlaser contains the following key contributions:
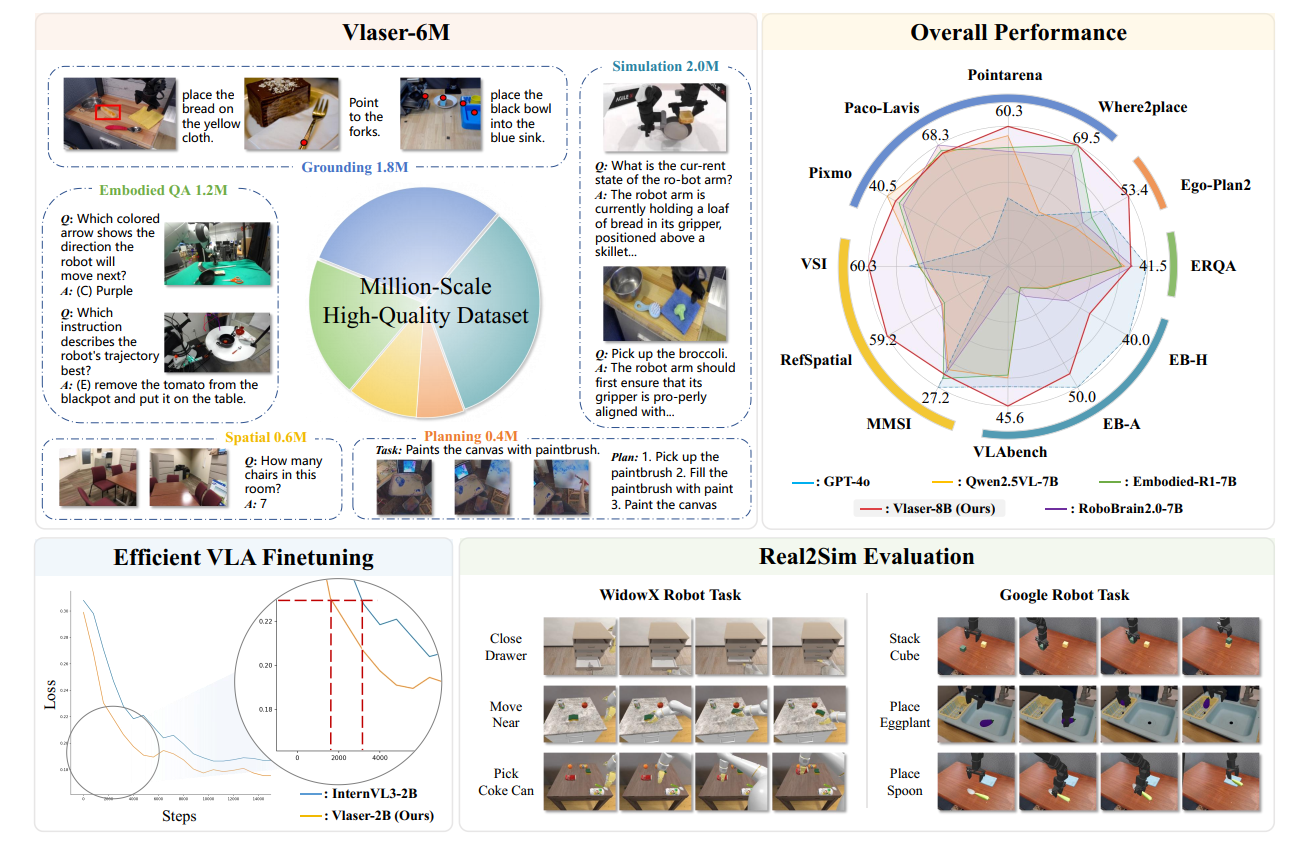
- We propose Vlaser-6M dataset, which comprises multi-task embodied reasoning data sources including embodied QA, grounding, spaital intelligence, planning as well as in-domain simulation-sourced data.
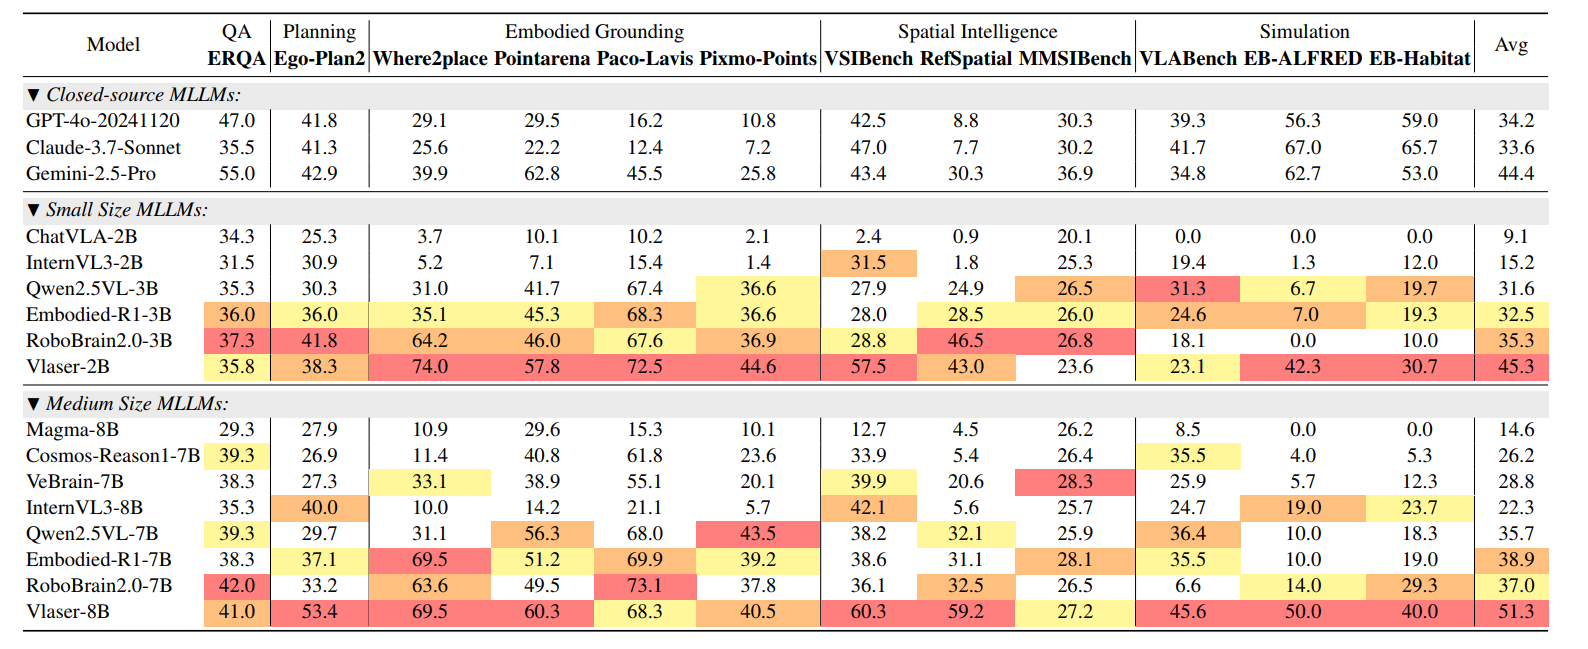
- Vlaser-8B achieves state-of-the-art embodied reasoning capabilities compared to other embodied reasoning VLMs.
- The pretrained Vlaser VLM significantly accelerates convergence in downstream VLA policy learning.
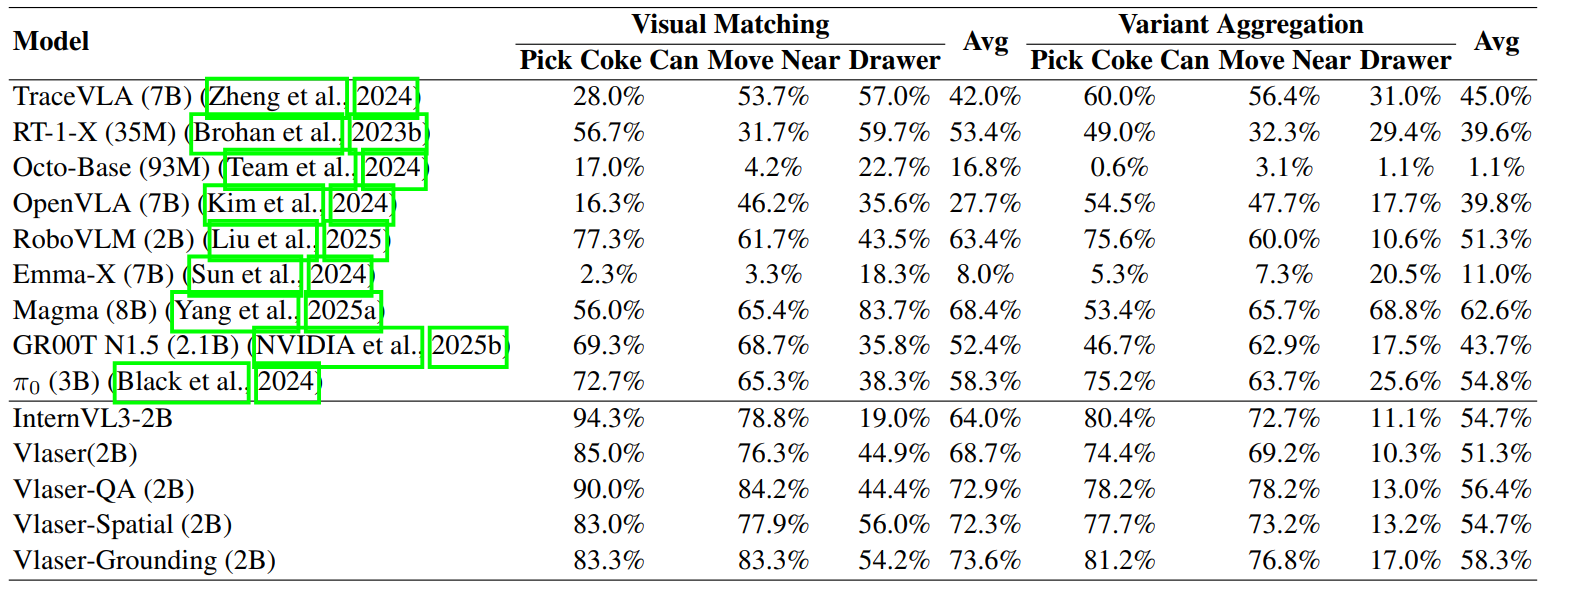
- Vlaser VLA achieves state-of-the-art results on the WidowX benchmark and competitive performance on the Google Robot benchmark on downstream closed-loop simulation evaluation.
Vlaser Architecture
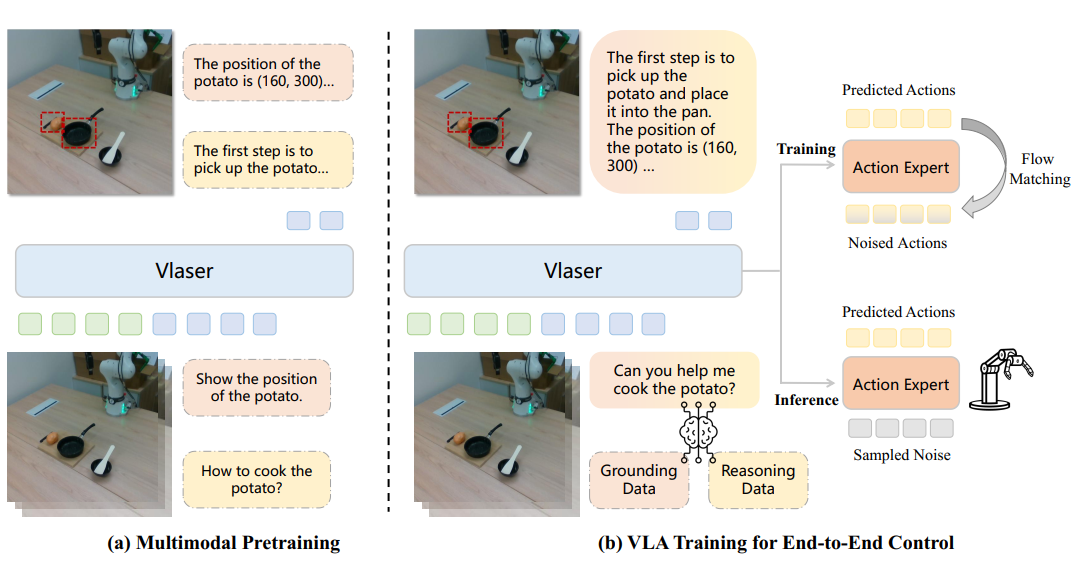
Vlaser adopts a two-stage training recipe, designed to optimize both embodied reasoning and end-to-end robot control. It includes a VLM pretraining followed by a VLA finetuning:
- (1) VLM Pretraining. The multimodal pretraining process for Vlaser is conducted by supervised fine-tuning (SFT) on Vlaser-6M dataset based on InternVL3 to empower VLM with stronger embodied reasoning capability.
- (2) VLA Finetuning. Vlaser-VLA is finetuned by incorporating a flow-matching-based action expert on robot-specific datasets.
Performance
Embodied Reasoning Capability
Closed-loop Evaluation on WidowX
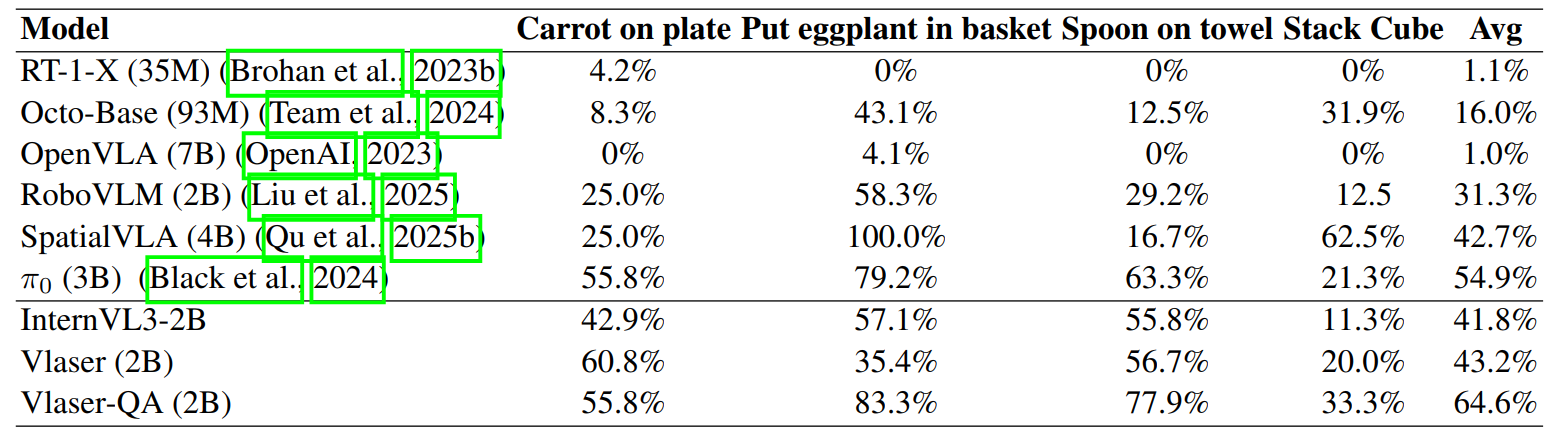
Closed-loop Evaluation on Google Robot
Citation
        @article{yang2025vlaser,
          title={Vlaser: Vision-Language-Action Model with Synergistic Embodied Reasoning},
          author={Yang, Ganlin and Zhang, Tianyi and Hao, Haoran and Wang, Weiyun and Liu, Yibin and Wang, Dehui and Chen, Guanzhou and Cai, Zijian and Chen, Junting and Su, Weijie and others},
          journal={arXiv preprint arXiv:2510.11027},
          year={2025}
        }
Acknowledgement
This website is adapted from Nerfies, licensed under a Creative Commons Attribution-ShareAlike 4.0 International License.